Audio Sandbox.
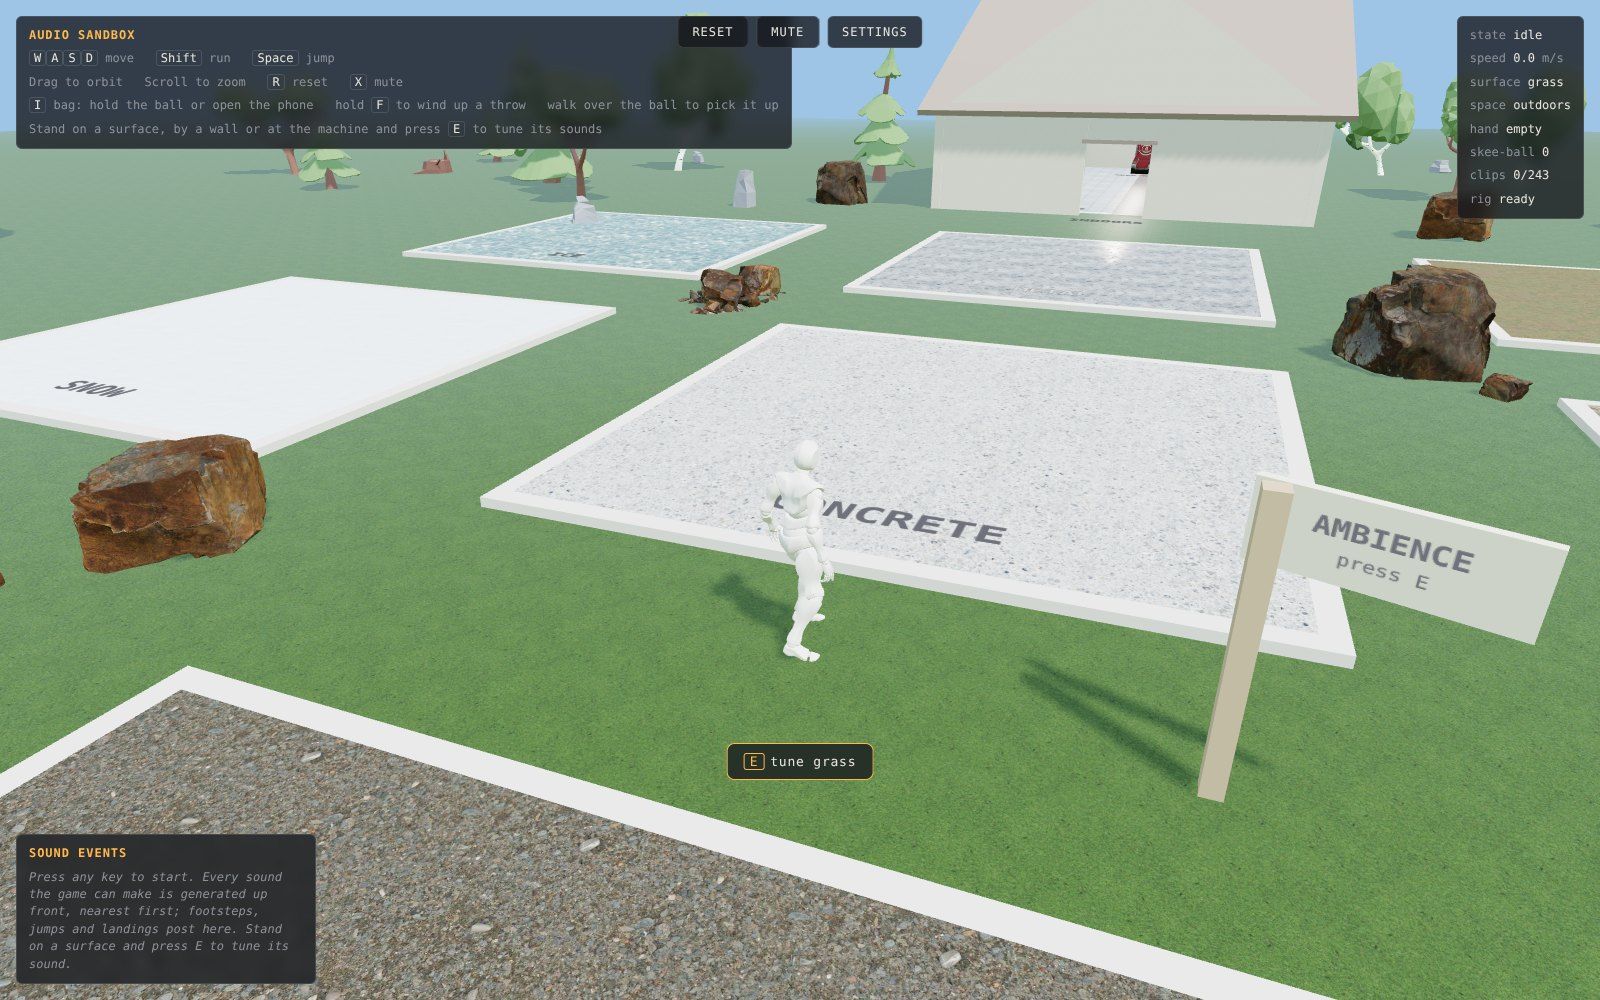
A third-person 3D playground where every sound effect is generated by Stable Audio 3 as you play.

Project Details

@maxfieldhulkerSAI
Builder since 2026
- Published
- 11/05/2026
- Model
- Stable Audio 3.0 Large
- Hosting
- API
- License
- MIT
Endpoints Used
- Text to Audio
What It Does
You walk a character around a grass field with nine surface pads (concrete, gravel, ice, metal, moss, sand, slate, snow, water), a small indoor room with wood and linoleum floors, some walls to throw at (brick, plaster, sheet metal, glass, a plank fence), a bag with a ball and a phone in it, and a skee-ball machine. Every footstep, jump, landing, ball bounce, score chime, menu click and the ambience bed is a clip generated by Stable Audio 3 from a prompt template. On first load the game generates the whole sound set, nearest things first, then plays from cache. Stand on a surface, next to a wall, or at the machine and press E to open a tuning card: describe what it should sound like, regenerate, audition the takes, pick one. The phone in your bag opens Stable Stack, a merge puzzle game whose sounds were made the same way.
Code Snippets
curl -X POST https://api.stability.ai/v2beta/audio/stable-audio/text-to-audio \
  -H "Authorization: Bearer $STABILITY_API_KEY" \
  -F model=stable-audio-3 \
  -F prompt="A punchy lo-fi drum loop with dusty vinyl crackle, 90 BPM." \
  -F duration=30 \
  -o result.mp3
How It Uses Stable Audio
Text to Audio
Generates every sound effect. One call per take, with model=stable-audio-3, duration from 1 s (footsteps) to 30 s (the ambience bed), steps 8 and cfg_scale 7 by default (both adjustable in Settings), a random seed, and output_format mp3 or wav.
Explore more projectsjust like this one.
 Stable Audio 3.0 LargeLocalAPI
Sculptro
Javor Vatchkov
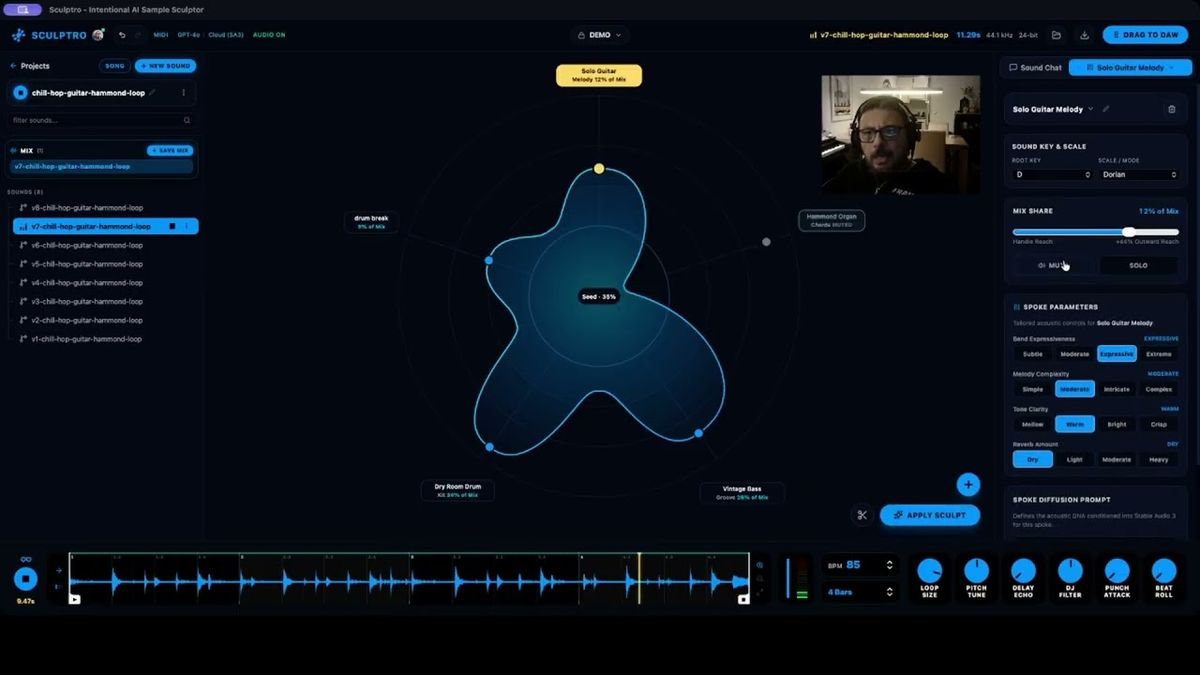
SCULPTRO is a native AI sound-sculpting instrument powered by Stable Audio 3 that turns any text prompt into an interactive spider diagram of custom sonic spokes, each with its own generated acoustic parameters, so producers can shape, inpaint, layer, and drag WAV samples straight into their DAW.
 Stable Audio 3.0 LargeLocal
Audio Studio Mcp
@kanaworksai-hue
Audio Studio MCP gives Claude Code, Claude Desktop, Cursor and any other MCP client a sound studio that runs on your own Mac or Windows PC
 Stable Audio 3.0 LargeAPI
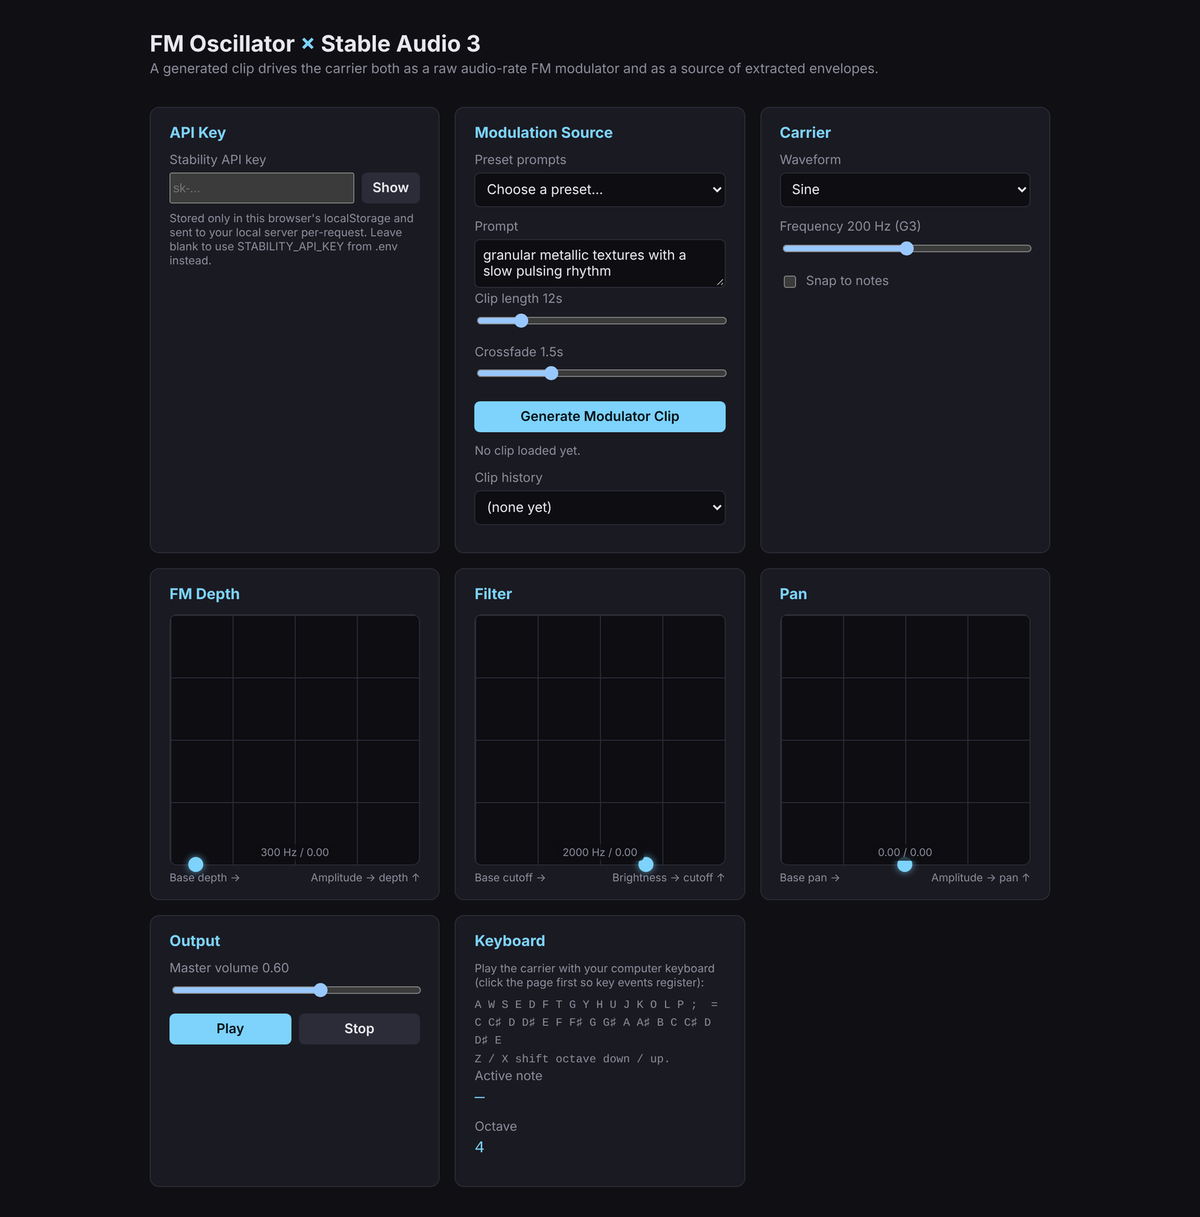
FM Oscillator × Stable Audio 3
@maxfieldhulkerSAI
A real-time FM synthesizer whose modulator is a generated Stable Audio 3 clip.
 Stable Audio 3.0 LargeAPI
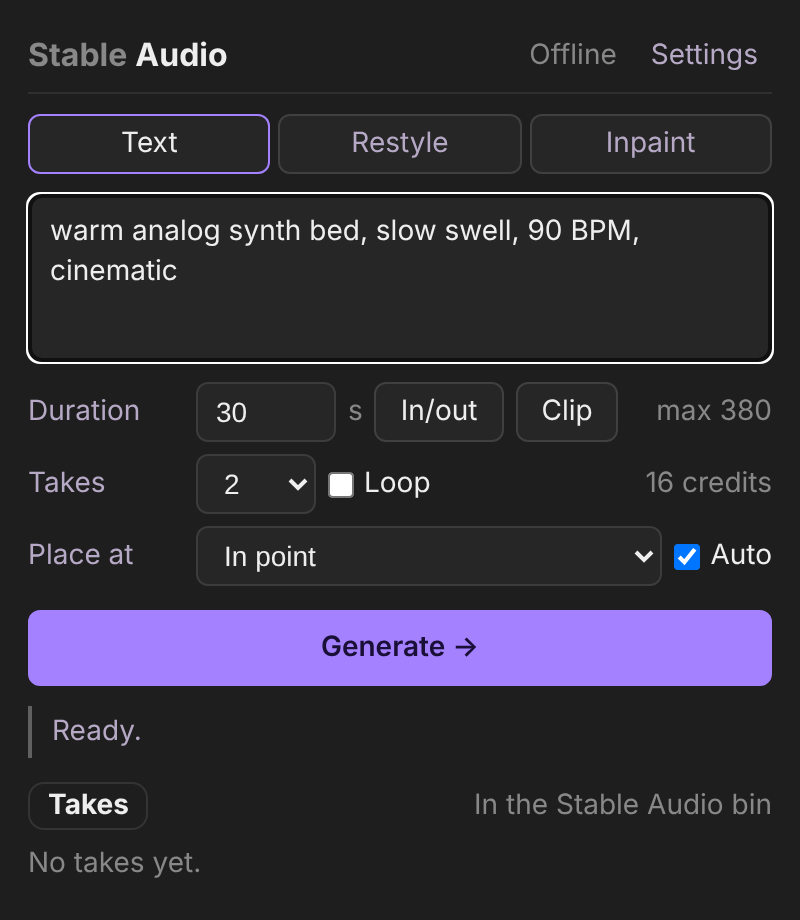
Stable Audio for Premiere Pro
@maxfieldhulkerSAI
A Premiere Pro panel that generates music and sound design with Stable Audio 3 and places the result on your timeline.